Python pipelines for data and AI.
Prepare training and evaluation datasets, process multimodal data with Python libraries, and generate embeddings alongside SQL transformations. Sail runs Python inside its Rust-native engine.


Python runs inside the engine.
AI data work runs through Python: model libraries, file parsers, tokenizers. Where that Python runs decides whether every batch is copied between processes to reach it.
Spark runs Python UDFs in separate worker processes. Each batch is serialized out of the JVM, sent to the worker, and the results come back the same way. Arrow makes the format cheaper; the trip remains.
Sail embeds Python in its Rust engine. Arrow UDFs read the engine’s Arrow buffers directly, with no second process and no copy.
Built from Spark APIs you already know.
A multimodal pipeline on Sail is DataFrame and SQL code, with your Python where the model work happens.
-
Files become rows
Start from a table of file paths and spread it across tasks. Each task reads its own PDFs, images, audio, or video and returns only what later steps need.
pdfs = spark.createDataFrame([(p,) for p in paths], "path string").repartition(2)ocr-scanned-pdfs/main.py -
Models run on Arrow batches
mapInArrow and Pandas UDFs pass batches to your Python inside the engine. Load a model once per partition, then score every batch.
vectors_out = (chunks.select("chunk_id", "text").repartition(2).mapInArrow(embed, "chunk_id string, embedding array<float>"))pdf-search/main.py -
Vectors are a column
Store embeddings as array<float> and rank them in SQL by cosine similarity, inner product, or L2 distance.
F.expr("vector_cosine_similarity(text_vec, image_vec)") \.cast("double").alias("score")search-images-by-text/main.py -
Ask a model from SQL
Sail adds Jev functions to Spark SQL. Each call asks one of TypeSafe’s Jev models a question about a row. Apache Spark has no equivalent.
Jev in SailSELECT text, jev_choice(text,'Which team should handle this support ticket?',map({criteria})) AS answerFROM (SELECT DISTINCT text FROM tickets)jev-sql-routing/main.py -
Check quality, then write tables
Measure results with ordinary SQL, then write them to Parquet or Delta Lake for training, evaluation, or retrieval.
scored = transcripts.select("id","seconds","transcript",F.levenshtein(normalized("transcript"), normalized("reference")).alias("edits"),F.length(normalized("reference")).alias("reference_chars"),)transcribe-audio/main.py
The code, and what it returned.
Each runs end to end on real files, most with open models. The code is the example’s own, and the result is what its tests or README report.
The CLIP encoders run inside mapInArrow. Ranking is one SQL function over the stored vectors.
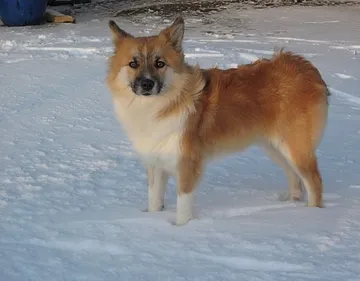 “a dog playing in the snow”
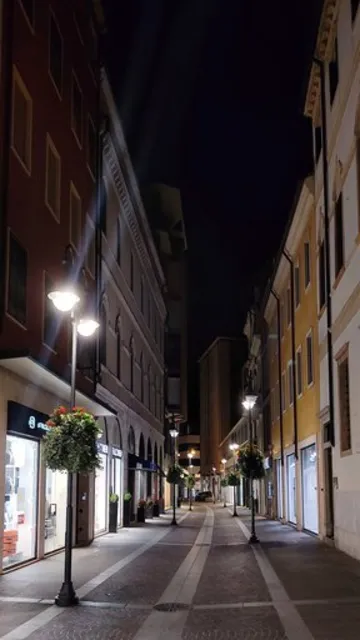 “a city street at night”
- Photos from Wikimedia Commons, CC0 and US public domain
- CLIP ViT-B/32 on ONNX Runtime
- CPU
Bring your next AI data pipeline.
Explore training data preparation, embeddings, or model scoring with a LakeSail engineer.